The Multi-Dimensional
Data Platform for
Analytics, Engineering & AI.
D-Modulus (Data Modulus) extracts the absolute value of data (|Data|) by eliminating synthetic warehouse credit taxes and vendor silos. Tesseract is the multi-dimensional hypercube engine that unifies Data Analytics, Data Engineering, and Native AI/ML on open Apache Iceberg storage. The 78% lower-cost alternative to Snowflake and Databricks with 0% compute markup.
Why D-Modulus? Why Tesseract?
Traditional databases project complex enterprise operations onto flat, 2D spreadsheets and force you to buy overpriced virtual warehouse credits to query them. We engineered a mathematically sovereign alternative.
D-Modulus = Data Modulus (|Data|)
The Absolute Value of DataIn mathematics, the modulus |x| extracts the absolute magnitude by stripping away signs, noise, and distortions. D-Modulus strips away synthetic cloud warehouse credits, vendor markup taxes, and data silo discrepancies to reveal the absolute, undeniable ground truth of your enterprise metrics.
Tesseract = Multi-Dimensional Intelligence
The 4-Dimensional HypercubeA tesseract is a 4D geometric hypercube. Enterprise data is not a flat table—it has infinite dimensions: temporal snapshots, streaming events, high-speed aggregations, vector embeddings, and machine learning models. Tesseract allows your team to traverse and analyze every dimension simultaneously in one unified plane.
Traverse the 5 Dimensions of Tesseract
Click across each dimension of the Tesseract unified platform to inspect how data engineering, interactive analytics, and AI/ML operate seamlessly on open Apache Iceberg storage.
Open Apache Iceberg with Zero Format Lock-in
Unlike Snowflake's proprietary micro-partitions or Databricks proprietary Delta extensions, Tesseract writes pure, open Apache Iceberg tables stored directly in your own AWS S3, Google Cloud Storage, or MinIO buckets.
- Real-time Debezium CDC: Stream PostgreSQL, MySQL, and Kafka events into Bronze tables with sub-second latency.
- Full ACID Transactions: Snapshot isolation, concurrent writes, and zero-corrupted partitions.
- Time-Travel & Branching: Query any historical snapshot at any point in time for auditing or rollbacks.
pipeline_id: "core_enterprise_stream"
source:
  type: "postgres_cdc"
  connection: "tesseract_secrets://prod_db"
  table: "public.orders"
transformations:
  - column: "customer_email"
    apply: ["mask_sha256", "lowercase"]
  - column: "gross_revenue"
    apply: ["cast_decimal(18,2)", "assert_positive"]
sink:
  table: "iceberg.gold.revenue_daily"
  partition_by: ["days(order_timestamp)"]
write_mode: "merge_on_read"Sub-Second Trino ANSI SQL Without Virtual Warehouse Tax
Stop burning expensive Snowflake credits waiting for virtual warehouses to resume. Tesseract's distributed Trino engine executes high-concurrency ANSI SQL queries directly against Iceberg metadata and object storage in under 24 milliseconds.
- Sub-24ms p95 Latency: Dynamic metadata caching and C++ vectorized execution.
- Federated Cross-Cloud Queries: Query PostgreSQL, MongoDB, Kafka, and S3 in a single SQL statement.
- Complete BI Tool Integration: Plug in Tableau, PowerBI, Superset, or Hex via standard JDBC/ODBC.
-- Cross-source federated ANSI SQL query
SELECT
    c.region,
    date_trunc('day', o.order_timestamp) AS sale_day,
    count(DISTINCT o.order_id) AS total_orders,
    sum(o.gross_revenue) AS total_revenue,
    avg(t.telematics_latency_ms) AS avg_latency
FROM iceberg.gold.revenue_daily o
JOIN postgres.public.customers c
    ON o.customer_id = c.id
JOIN kafka.realtime.fleet_telematics t
    ON o.dispatch_id = t.dispatch_id
WHERE o.order_timestamp >= current_date - INTERVAL '7' DAY
GROUP BY 1, 2
ORDER BY total_revenue DESC;Visual DAG Pipelines & Dynamic PySpark Compute
Databricks forces you into expensive DBU compute multipliers with long cluster boot times. Tesseract gives you an intuitive visual DAG builder, automated SQLMesh lineage, and dynamic Spark clusters that scale to zero immediately upon job completion.
- Full Databricks dbutils Parity: Import your existing PySpark notebooks with 100% dbutils secrets and file system compatibility.
- 204 Built-in Column Transforms: Declarative transformations without writing redundant boilerplate.
- Dynamic Airflow DAG Compilation: Automatically compiles visual pipelines into production Airflow workflows.
from dmodulus.dbutils import dbutils
from pyspark.sql import functions as F

# Native Databricks dbutils secrets compatibility
api_key = dbutils.secrets.get(scope="core_ai", key="vector_key")
s3_path = dbutils.widgets.get("target_zone")

# Distributed Spark DataFrame transformation
df = spark.read.table("iceberg.silver.customer_telemetry")
clean_df = df.filter(F.col("event_status") == "CONFIRMED")              .withColumn("modulus_score", F.abs(F.col("variance")))

clean_df.writeTo("iceberg.gold.customer_360").append()
print(f"Auto-scaled Spark: Job completed, cluster scaling to zero.")Run Vector RAG & Agentic LLMs Directly on Iceberg
Stop paying SaaS vector host bills and dangerous data egress fees. Tesseract embeds vector indexing directly into your Apache Iceberg tables. Train, evaluate, and deploy agentic AI pipelines inside your sovereign VPC.
- In-Lake Vector Storage: Colocated embeddings eliminate brittle ETL sync between lakehouse and vector databases.
- Sub-50ms Hybrid Semantic Retrieval: Combines keyword filtering with dense vector similarity via Trino.
- Autonomous Copilot Agents: Natural language to SQL, automatic schema healing, and predictive cluster optimization.
from dmodulus.ai import RAGPipeline, EmbeddingJob

# Vectorize directly from Gold Iceberg table
pipeline = RAGPipeline(
    name="enterprise_knowledge_base",
    source_table="iceberg.gold.customer_support_docs",
    chunking={"strategy": "semantic_recursive", "chunk_size": 512},
    embedding_model="text-embedding-3-small",
    in_lake_vector_sink="iceberg.ai.vectors_customer_index"
)

# Execute distributed indexing on ephemeral Spark
job = pipeline.execute_distributed(executors=4)
print(f"Successfully indexed {job.total_chunks} vectors in-lake.")0% Compute Markup: Pure In-VPC Cost Efficiency
Cloud warehouse providers mark up raw compute by 200% to 400% through synthetic credits and DBUs. Tesseract operates under the Data Modulus principle: pay only for the exact cloud compute instances you use, with zero markup.
- 100% Bring-Your-Own-Cloud (BYOC): Runs in your AWS, GCP, Azure, or private Kubernetes cluster.
- Real-Time Pod & Worker Metering: Transparent dollar-per-query attribution across teams and departments.
- Automated Spot Instance Harvesting: Run batch ETL on ephemeral EC2 spot instances for up to 90% savings.
{
  "enterprise_organization": "Global Fintech Corp",
  "workload_engine": "Tesseract Dynamic Spark & Trino",
  "underlying_instances": "AWS EC2 c6i.4xlarge (Spot)",
  "raw_cloud_cost": "$4,120.00",
  "tesseract_compute_markup": "$0.00 (0.0%)",
  "snowflake_equivalent_credits": "$18,450.00",
  "databricks_equivalent_dbu": "$16,800.00",
  "net_monthly_savings": "$14,330.00 (77.7%)"
}Why Data Leaders Choose Tesseract
How Tesseract by D-Modulus directly compares to legacy cloud warehouses and proprietary lakehouse stacks.
| Capability / Dimension |
Tesseract Lakehouse
Recommended
|
Snowflake | Databricks |
|---|---|---|---|
| Storage Standard | 100% Open Apache Iceberg | Proprietary Micro-partitions | Delta Lake (Proprietary features) |
| Compute Pricing Markup | 0% Markup (Raw In-VPC Compute) | Credits (Up to 300% markup) | DBUs + VM Cloud Invoices |
| Deployment Sovereignty | 100% In-VPC / Sovereign BYOC | Multi-Tenant SaaS Cloud | Control Plane SaaS Required |
| Interactive SQL Latency | <24ms p95 (Trino ANSI SQL) | Fast, but virtual warehouse spin-up | Slower boot on SQL warehouses |
| Data Engineering & DAGs | Visual DAGs + Airflow + SQLMesh | Snowpark / External Airflow needed | Databricks Workflows (Complex UI) |
| Notebook Compatibility | Native dbutils & PySpark Parity | Limited Python / Notebook IDE | Native Databricks Notebooks |
| Native Enterprise AI & RAG | In-Lake Vector Indexing + Copilot | Cortex AI (Costly Premium Add-on) | MosaicML (Separate Complex Stack) |
| Data Egress Fees | $0.00 (Data never leaves your cloud) | High egress tolls to external tools | Variable cross-region transfer fees |
| Average Annual TCO | 74% – 78% Savings (0% Markup) | High / Unpredictable Burn | High / DBU Multiplier Risk |
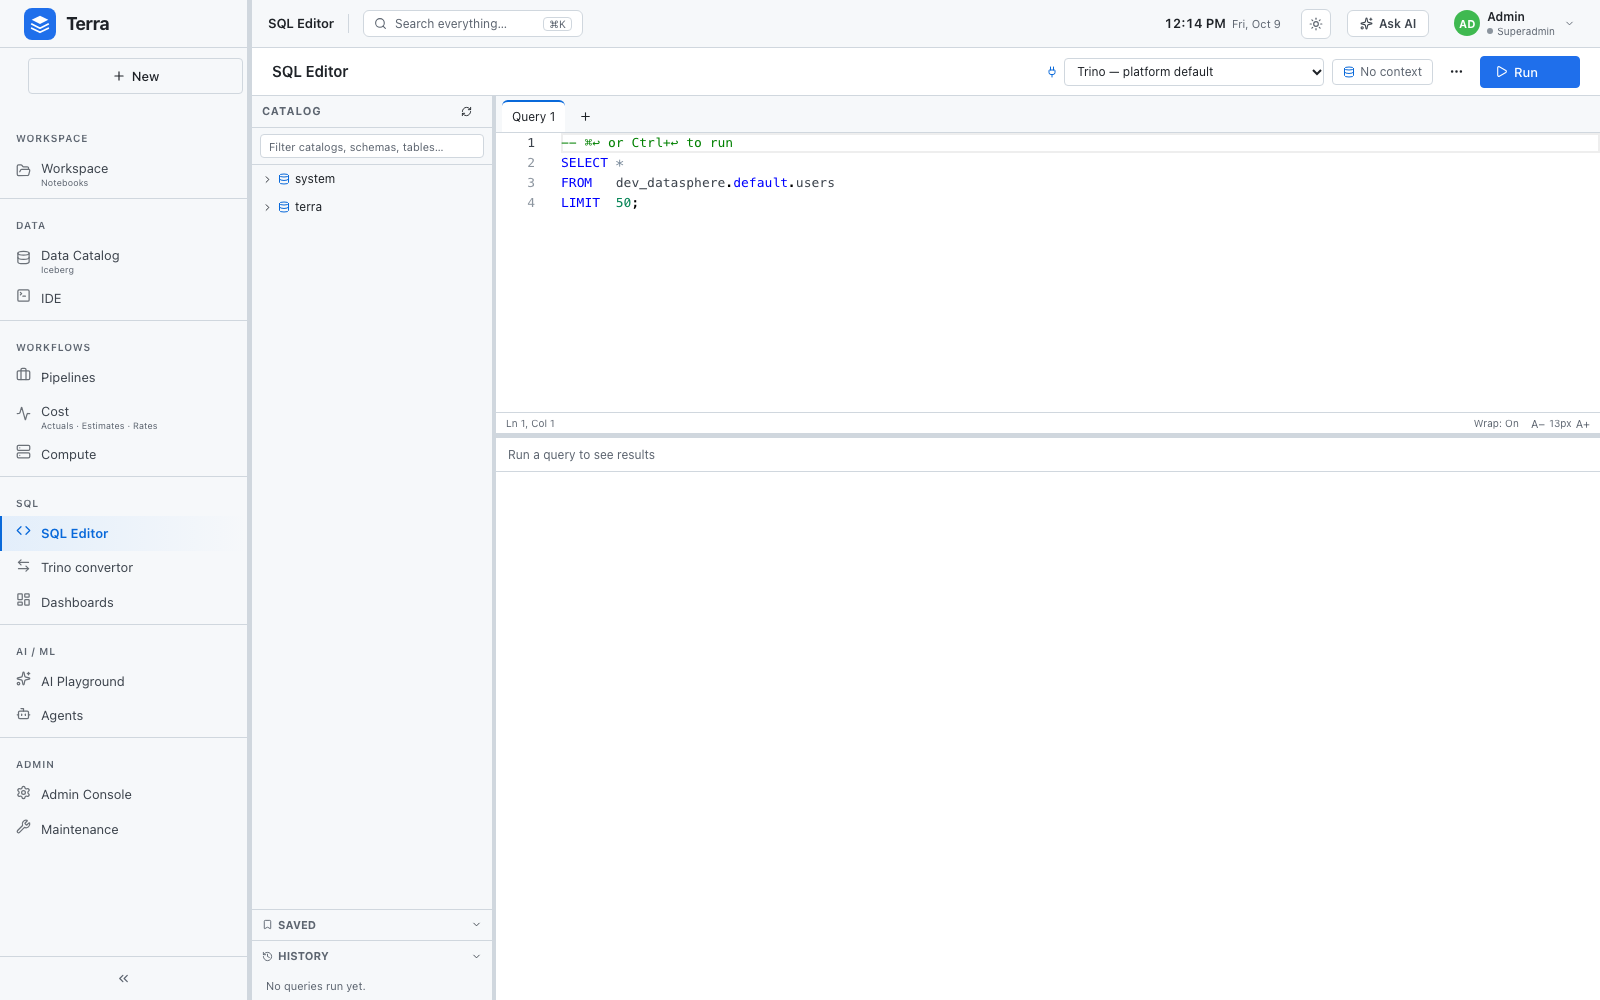
The Single-Pane Tesseract Experience
No fragmented consoles, no disjointed logins. Experience the sovereign control plane uniting SQL, visual pipelines, and AI copilot.
Calculate Your Snowflake & Databricks Savings
Slide your current monthly cloud warehouse spend to see the immediate annual savings achieved by switching to D-Modulus Tesseract.
We bill a predictable software license. Your data stays in your cloud storage, and your queries run on raw cloud compute with 0% vendor markup.
Engineered for Complete Enterprise Sovereignty
Your data gravity belongs to you. Tesseract is deployed directly within your own cloud boundary with zero external egress.
100% BYOC In-VPC
Deploy inside AWS, GCP, Azure, or on-prem Kubernetes.
Zero Data Egress
Data and metadata never leave your private corporate boundary.
SOC2 & HIPAA Ready
Column-level masking, automated encryption, and audit logs.
100% Open Standards
Apache Iceberg, Trino, PySpark, Airflow & OpenSearch.
From the Architecture Blog
Tesseract vs. Snowflake vs. Databricks: 2026 Lakehouse Architecture Comparison
Why modern enterprises are abandoning proprietary credit markups and format lock-in in favor of multi-dimensional sovereign lakehouses.
The Mathematics of D-Modulus: How the Absolute Value of Data Cuts Costs by 78%
In mathematics, |x| removes sign distortion. Learn how D-Modulus eliminates cloud markup noise to extract the pure ground truth of your business data.
End-to-End RAG Pipelines from Iceberg Tables to Vector Embeddings
The AI engineer playbook: build enterprise vector search and agentic copilot pipelines directly on Iceberg without paying external SaaS vector tolls.
Everything You Need to Know About Tesseract
Get answers to the most common architectural, migration, and cost questions from engineering leaders.
What does D-Modulus mean, and why is the flagship product called Tesseract?
In mathematics, the modulus operator |x| returns the absolute value of a quantity—stripping away artificial signs and distortions to reveal fundamental magnitude. D-Modulus stands for Data Modulus: extracting the absolute, unadulterated value of enterprise data without paying synthetic cloud warehouse credit taxes or drowning in data silos. A Tesseract is a 4-dimensional hypercube. Modern business data has multiple interconnected dimensions: operational transactions, analytical aggregations, vector semantics, temporal time-travel snapshots, and FinOps costs. Tesseract allows you to traverse and query all dimensions in one unified lakehouse plane.
How is Tesseract an alternative to Snowflake and Databricks?
Snowflake locks your data into proprietary micro-partitions and marks up virtual warehouse compute credits by up to 300%. Databricks layers expensive DBU multipliers and suffers from slow notebook startup and fragmented tools. Tesseract unifies the entire stack: open Apache Iceberg storage in your own cloud buckets, sub-second Trino ANSI SQL for interactive BI, dynamic PySpark engineering with full Databricks dbutils compatibility, and native in-lake AI & RAG vector indexing. Because Tesseract runs inside your VPC with 0% compute markup, customers typically reduce their annual data platform TCO by 74% to 78%.
Can I migrate existing Databricks notebooks and PySpark pipelines without rewriting code?
Yes! Tesseract includes built-in parity for the Databricks dbutils API, including dbutils.secrets, dbutils.fs, and notebook parameter widgets. Your existing PySpark dataframes and SQL statements execute natively against Iceberg tables with zero refactoring.
How does Tesseract deploy inside my enterprise infrastructure?
Tesseract is delivered as a 100% Bring-Your-Own-Cloud (BYOC) architecture or Kubernetes Helm deployment. It installs cleanly into your AWS VPC, Google Cloud project, Microsoft Azure subscription, or on-premises Kubernetes cluster. Data and metadata never leave your corporate security perimeter.
Extract the Absolute Value of Your Data.
Eliminate cloud warehouse taxes and vendor lock-in. Consolidate your analytics, data engineering, and AI/ML onto Tesseract by D-Modulus today.